Corrective RAG
A corrective retrieval pipeline that detects weak context, rewrites queries, searches again and reranks evidence before answering.
A production-oriented RAG experiment focused on the failure mode that matters most: what happens when first-pass retrieval is irrelevant or incomplete.
Search less.
Find evidence faster.
The problem worth solving.
Conventional RAG can produce confident but poorly grounded answers when retrieval returns irrelevant documents or misses the right evidence.
A focused path to the solution.
Combined dense + BM25 hybrid retrieval with document grading, conditional routing, query transformation, optional web search, reranking and a corrective retry loop.
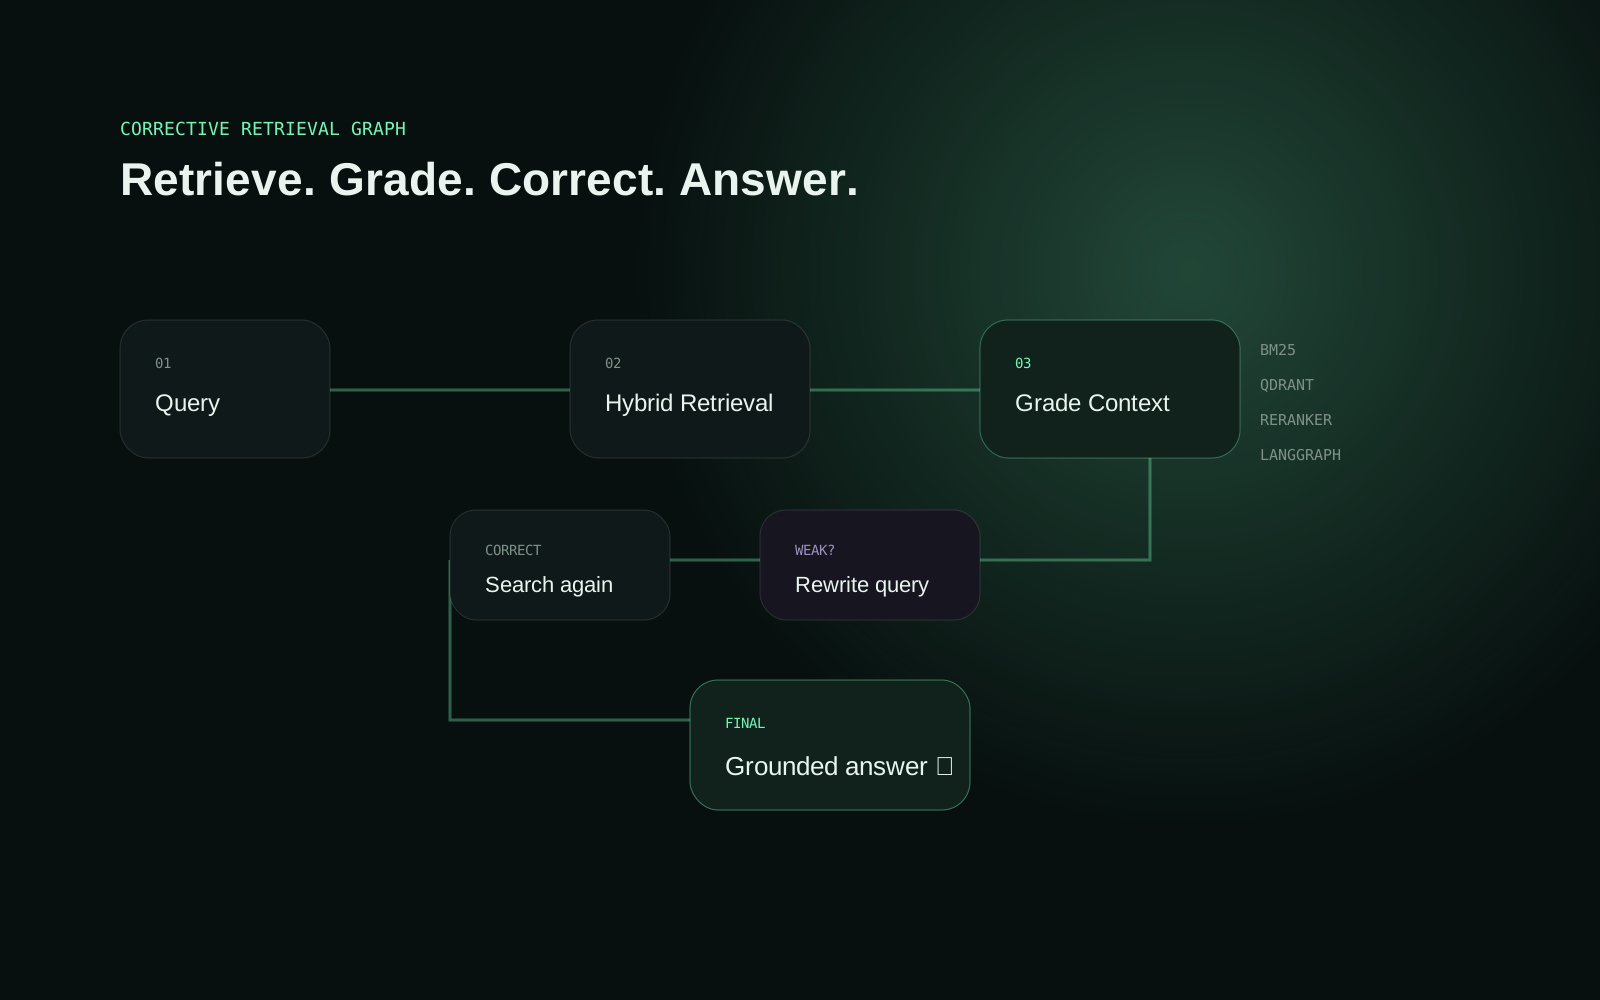
How the system flows.
Each stage has one clear job: prepare the documents, index meaning, retrieve context, and generate the final response from that context.
Query
Hybrid retrieval
Document grading
Relevant?
Query rewrite
Corrective retrieval
Reranking
Grounded answer
More than an
LLM text box.
The value is in the retrieval system around the model: document preparation, semantic search, context selection, evaluation, and a usable interface.
Dense + lexical hybrid search
Conditional LangGraph correction loop
Query rewrite when evidence is weak
Reranking and citation-aware response generation
A focused stack for document intelligence.
What the project delivered.
A more resilient answering pipeline that explicitly checks retrieval quality before generation and returns grounded answers with citations when evidence is available.
Have a product idea worth building?
I build practical AI applications with a focus on clear product value and reliable engineering.